WIDEBAND · Technology systems integrator

We build and run IT systems.

Servers, networks, databases and software. We connect them, keep them running and develop them as your needs change.

WIDEBAND since 2014. About us Our founder has worked with systems and networks since 2001 — 25+ years of experience.
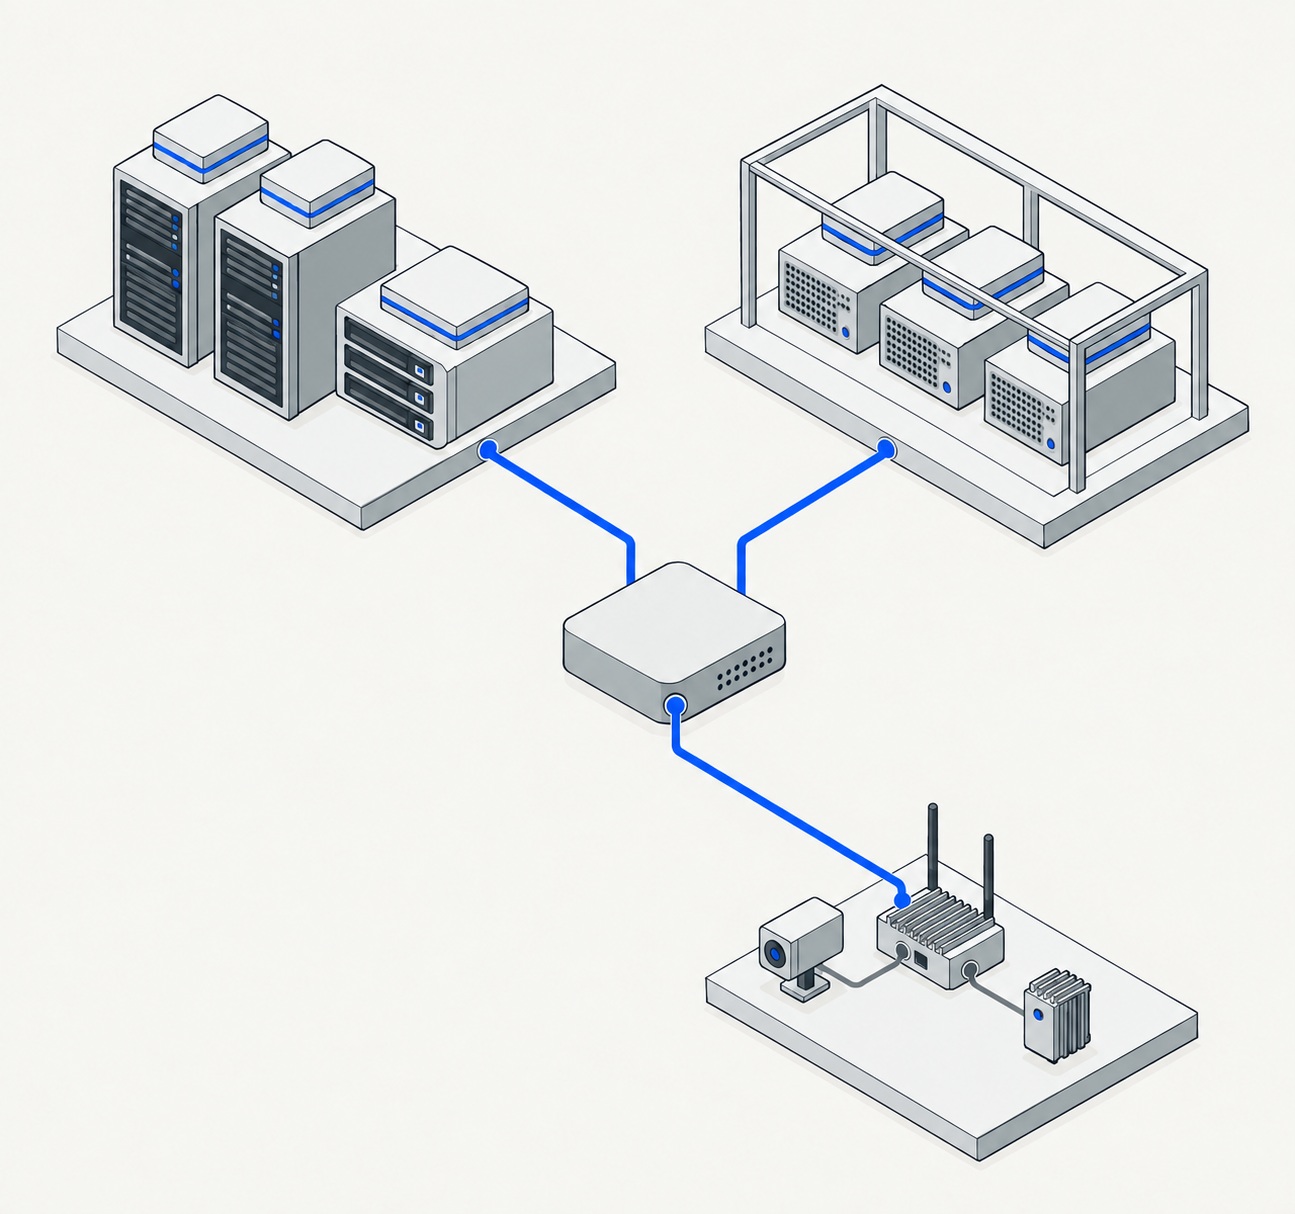
A network connects on-premises servers, cloud resources and an edge gateway with two local devices. Application modules sit on the computing resources.
Illustrative connections between environments. Architecture is tailored to each project.

Modular compute containers for AI.

We build containerized compute modules with servers and GPUs at solar and wind farm sites for AI workloads.

Explore AI infrastructure
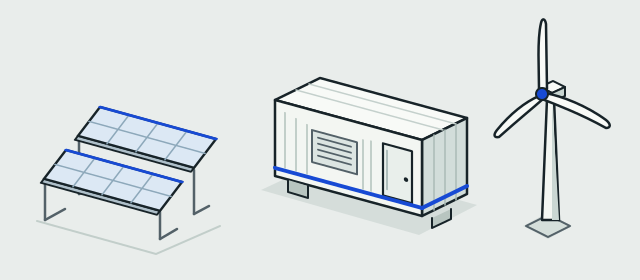
A compute container is shown between solar panels and a wind turbine.
Solar panelsAI containerWind turbine

At the farm site

A conceptual site view: the compute container can be placed at a solar or wind farm.
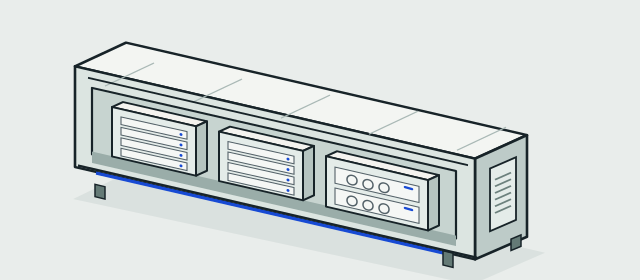
A cutaway compute container shows server racks and GPU modules.
ServersGPU modules

Inside the module

Servers and GPUs provide the computing resources for AI workloads.

What we do

Infrastructure, networks and software, from architecture to daily operations.

Explore solutions

Infrastructure

  • Linux & Servers
  • Virtualization
  • Storage
  • Backup & Disaster Recovery
  • High Availability

Cloud

  • Public Cloud
  • Private Cloud
  • Hybrid Cloud
  • Cloud Migration
  • Kubernetes / OpenShift

Networking

  • Private 5G networks (5G MPNs)
  • LAN / WAN
  • VPN
  • SD-WAN
  • Firewalls
  • Network Segmentation
  • Wireless
  • Edge

Software

  • Custom Applications
  • Backend Systems
  • APIs
  • Integrations
  • Automation
  • Internal Platforms

AI & language models

  • Public APIs, including OpenRouter
  • Locally hosted LLMs
  • Private inference
  • Model training and fine-tuning
  • Application integration

Security

  • Infrastructure Hardening
  • IAM
  • Network Security
  • Monitoring
  • Backup
  • Security Architecture

Operations

  • Managed Infrastructure
  • Monitoring
  • Incident Response
  • Patch Management
  • Capacity Management
  • Infrastructure Lifecycle

Language models, in the cloud or on your own servers.

In our own lab, we test LLM integrations, local deployments and model training approaches. We use it to assess response quality, resource needs and data flows before deciding how a solution should run in production. Whether you use a public API such as OpenRouter or keep the model within your own infrastructure, we connect it to the applications and workflows that need it.

Explore AI and LLM deployments

Tell us about your project.

Describe your systems and what you want to change.

Contact us